Most teams that set out to build a private AI server start at the GPU and work outward. That order gets expensive quickly. The chassis gets picked before anyone knows the context length, the network gets ordered before the storage tier is scoped, and facilities finds out about a 60 kW rack the week it arrives on a pallet.
The right order is the reverse. Workload defines model, model defines VRAM, VRAM defines GPU class, GPU class defines chassis, chassis defines power and cooling, and only then does the software stack sit cleanly on top. This guide walks that sequence end to end so you can hand a single checklist to procurement and facilities before the first vendor call. It assumes you are deciding what to buy, not what to rent.
Start With the Workload, Not the Hardware
Write down the three things that drive every downstream decision: which models you intend to serve, how many concurrent users will hit them, and what the longest realistic context window looks like. A 20-person legal team running an 8B summarizer on 8k context is a different machine from a 300-person engineering org running a 70B coding assistant with 128k context and RAG on top. Both are "private AI." Neither sizing works for the other.
Decide early whether this box is for inference only, inference plus light fine-tuning (LoRA, QLoRA), or full training. Training changes the memory math by roughly an order of magnitude and pushes you toward NVLink-class interconnect rather than PCIe. If you only need inference, say so and stop paying for training-grade fabric. If you are not sure, a short discovery sprint usually settles it faster than a spreadsheet, and our AI development process page walks through what that looks like.
Pick GPUs and VRAM From the Model, Not the Brochure
Model memory is the hard constraint. A Llama 3.1 70B model needs about 140 GB in FP16, or closer to 178 GB once you add KV cache and overhead. Drop the same model to INT4 (AWQ) and it fits in roughly 35 to 45 GB, a 68 to 75 percent reduction. That one decision changes whether a workload needs two GPUs or eight.
Quantization is not free. INT8 typically cuts memory by about half with a 2 to 5 percent quality drop and a 1.5 to 2x speedup, while INT4 cuts memory by roughly 75 percent and delivers up to 2.4x faster inference. For most retrieval-heavy enterprise workloads the quality loss is invisible; for high-stakes extraction or regulated reasoning it may not be. Test on your own evaluation set before you commit the rack.
Interconnect matters as soon as a model has to span GPUs. The H100 provides 900 GB/s of bidirectional NVLink bandwidth per GPU, roughly 7x a PCIe Gen5 x16 link at 128 GB/s. For a 70B model split across four cards that difference is the gap between usable latency and a chatbot that stalls mid-sentence. On single-GPU inference, PCIe is fine.
If NVIDIA pricing or allocation is a problem, there are real alternatives. We cover the trade-offs in GPU alternatives to NVIDIA; the short version is that AMD MI300X and Intel Gaudi 3 are credible for inference, less so for training ecosystems today.
Choose a Chassis Class That Matches Scale
Once you know the GPU count and interconnect, the chassis almost picks itself. A single-user developer workstation is a different animal from a shared departmental server, and both are different from a multi-node cluster. Our four-size comparison lays out where each class breaks down:
- Desk: 1 to 2 GPUs, under a desk, office power. Right for pilots, prototyping, and single-user developer work.
- Rack: 4 to 8 GPUs in a 4U or 6U chassis. Right for a team of 20 to 200 on a shared model.
- Cluster: multiple nodes with high-speed fabric (InfiniBand or RoCE). Right for 70B+ serving at scale or any fine-tuning program.
- Edge: compact or ruggedized, often fanless or sealed. Right for offline sites, ships, clinics, factory floors.
If you want to translate your team size into a specific GPU count before talking to anyone, the hardware estimator does the arithmetic and the companion piece on sizing GPU capacity by team size explains the assumptions.
Plan Networking and Storage Before the Rack Arrives
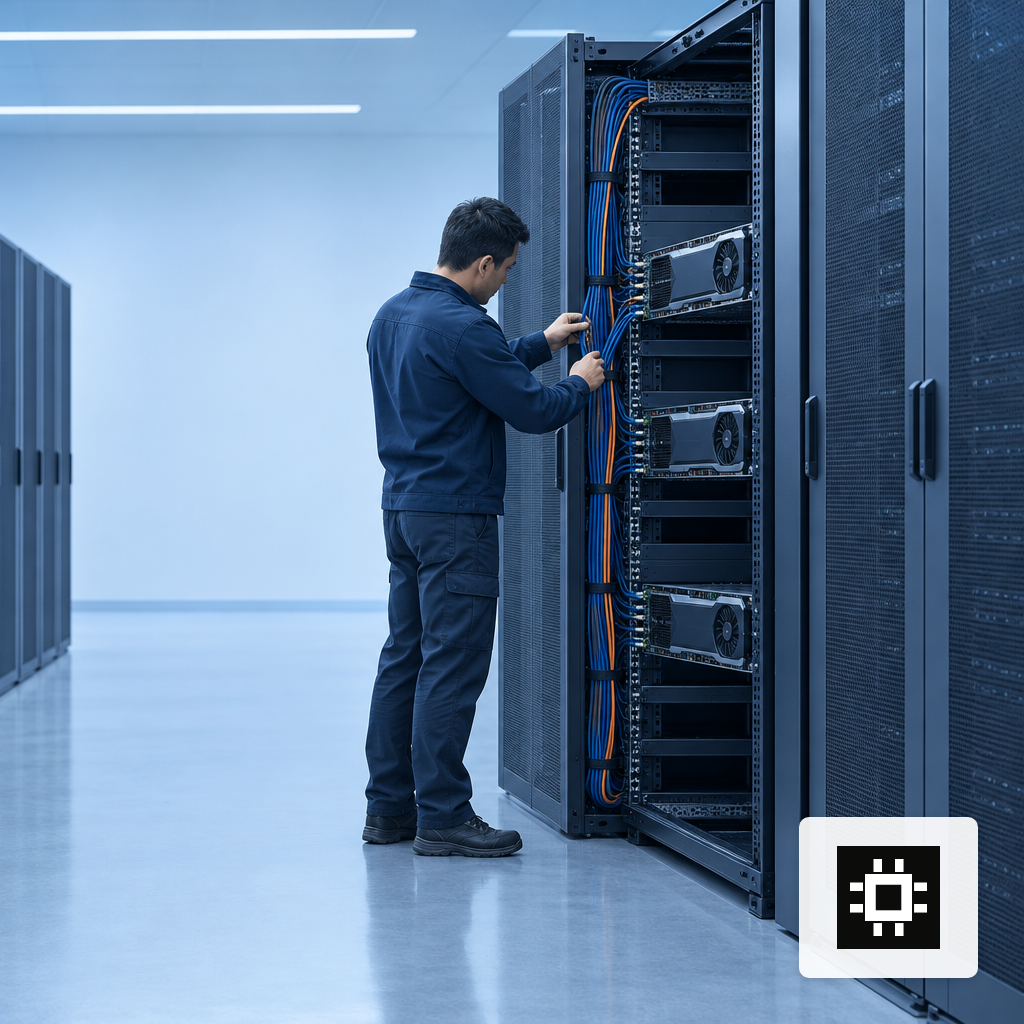
Two numbers decide the network. Within a node, GPU-to-GPU bandwidth has to match the model shard pattern. Between nodes, you need at least 100 GbE for anything above a single rack of inference, and 400 GbE or InfiniBand once you are training. Dual A+B feeds and redundant switches are not optional at this density.
Storage splits into three tiers in practice. A fast NVMe tier holds model weights and KV cache spill, sized at roughly 2 to 3x the total parameter footprint across all models you plan to host. A warm tier holds embeddings, vector indexes and recent documents. A bulk tier holds the source corpus and backups. Underestimating the NVMe tier is the single most common cause of cold-start latency on the first production day.
Select the Software Stack Deliberately
The hardware is half the system. The serving layer, orchestration, retrieval, access control, monitoring and governance are the other half, and they decide whether the box is actually usable on week three.
Serving should use continuous batching rather than naive batching. vLLM reports up to 23x throughput improvement over naive batching while reducing p50 latency, which is the difference between buying four GPUs and buying twelve. Pair that with a reverse proxy that handles auth, rate limits and audit logs rather than pushing those concerns into the model server.
Identity and audit matter more than most teams plan for. Tie the system into your existing identity provider through SAML, OAuth or OIDC rather than a local user table, and log every prompt, response and tool call. If you fall under the EU AI Act, deployers of high-risk systems must retain automated logs for at least six months and run Fundamental Rights Impact Assessments where required, with the Article 9 to 17 and Article 26 obligations becoming enforceable on August 2, 2026.
Address Power and Cooling Honestly
This is the section most teams underestimate. Modern GPU racks are not slightly denser than traditional IT; they are an order of magnitude denser. A current-generation AI rack draws between 40 kW and 142 kW depending on platform, with Hopper-class H100 racks landing around 30 to 45 kW. Traditional enterprise racks sit at 5 to 10 kW. If your facility was built for the latter, you are looking at electrical, PDU and cooling upgrades before the server lands.
Cooling follows power. Liquid cooling penetration in AI data centers is projected to rise from 14% in 2024 to 33% in 2025, pushed by Blackwell-class rack systems. If your target density is above 50 kW per rack, direct-to-chip liquid is effectively required. Below that, rear-door heat exchangers can bridge the gap on existing air-cooled rooms.
Which Workload and GPU Class Combinations Actually Fit
Not every workload belongs on every chassis. The grid below shows where the common combinations land for pain, where 1 is comfortable and 5 is actively bad for that pairing. It is a planning aid, not a benchmark.
Read the heatmap as a filter. Anything that scores 4 or 5 is a configuration you can rule out before writing a specification, which saves a round of vendor conversations.
Plan the Rollout, Not Just the Install
The install is a day. The rollout is a quarter. A realistic plan has three phases: a two-week discovery and sizing phase, an 8 to 12 week build and burn-in, and a 90-day production hardening phase where the real problems surface. We cover the latter in what breaks in the first 90 days; the short version is that storage, auth and monitoring fail before the GPUs do.
Decide the ownership model before the hardware ships. Who owns model updates, who owns the eval set, who approves a new agent going into production, and who gets paged at 2 a.m. when the vector database runs out of disk. If those names are not on the org chart on day one, the system drifts.
The Checklist Before You Talk to a Vendor
Hand this to procurement and facilities. If any line is blank, you are not ready to buy yet.
- Target models, quantization level and context length
- Peak concurrent users and tokens per second target
- Inference-only, LoRA, or full fine-tuning
- GPU count, VRAM per GPU, interconnect requirement
- Chassis class (Desk, Rack, Cluster, Edge)
- Network: in-node bandwidth, inter-node fabric, redundancy
- Storage: NVMe tier size, warm tier, bulk and backup
- Serving stack, identity provider, logging retention
- Rack power budget, PDU type, A+B feeds
- Cooling plan: air, rear-door, or direct-to-chip liquid
- Regulatory scope (HIPAA, SOC 2, GDPR, EU AI Act)
- Rollout owner, eval set owner, on-call rotation
Build the server in that order and the specification writes itself. If you want a second set of eyes on the sizing before you commit, get a quote and we will walk through the checklist with you.